



Working in a maintenance environment where the computerised maintenance management system (CMMS) has become the ultimate authority sometimes feels like being an extra in one of The Matrix films. Everyone is busy following the system. Tasks are created, moved, closed and measured. The system is treated as correct, even when the physical plant says otherwise. And there is no saviour coming to see through the system, challenge its authority and return technical judgement to the people who understand the machines.
We fear that artificial intelligence may make decisions for us and allow machines to rule the way we work in the future. Maintenance teams should perhaps look behind themselves instead. Long before AI became a serious topic, many organisations had already handed authority to systems, not because the software became intelligent, but because organisations stopped trusting their workforce to question it.
A static system ruling a dynamic operation
A CMMS can only generate and track what people structure and capture. It does not know whether a task is still relevant, whether the machine has changed, whether the allocated time is realistic or whether the work will prevent failure. Most implementations depend on fixed asset structures, planned durations and predefined workflows. The plant is dynamic, and its condition changes with load, production, maintenance quality and developing defects.
Condition monitoring is often presented as something that will reduce downtime, extend equipment life and improve reliability. However, no sensor, oil sample, thermal image, vibration spectrum or report can do that. Only maintenance action can. Condition monitoring tells us what is wrong, where it is wrong, why it is happening and, most critically, when maintenance must intervene. It should not simply be another task on the schedule. It should create a better schedule.
Every condition monitoring programme should begin with a scope defining the machines, technologies, frequencies and workload. The team should manage that scope and report compliance against it. Routine condition monitoring work should not be divided into thousands of CMMS tasks merely so the system can account for every hour. Where a machine already has an inspection or preventive-maintenance job card, the condition monitoring requirement can be included as a clear tick box. The CMMS should mainly receive the corrective work generated from the findings.
Today’s condition monitoring data-acquisition equipment is fast. But what is the value of speed if the team cannot reach the machines because the CMMS says the day is full? The schedule may allow four hours for an alignment. Waiting for production, permits, isolation and maintenance support turns it into seven. Work is postponed because the system still believes the original estimate. When condition monitoring identifies a developing failure mechanism, the schedule must change. Instead, every existing task stays, and the recommendation is added on top. One machine eventually carries hundreds of checks and recurring job cards, many closed with only an explanation for why they were not completed. That alone should force a technical review of whether every task, frequency and technology is still justified.
The schedule grows but is rarely cleared
At WearCheck, the consequences appear in its own reports. A developing failure mechanism is identified, and a corrective action is loaded. Month after month, the data shows the condition progressing. The recommendation sits open, is postponed or is closed with merely an administrative explanation. Eventually the warning period is gone. The failure mechanism has become an advanced defect, and failure may now be inevitable. Condition monitoring did not fail, the warning was there. The system simply recorded the months during which nobody took ownership.
The maintenance KPIs make this worse. One of the most important questions in weekly meetings has become: “Did we close all the work orders in SAP this week?” That measures administration, not reliability. The questions should rather be:
• Did we intervene in time?
• Was the recommended action correct?
• Did the machine condition improve?
• Did the defect return?
• Was the original diagnosis accurate?
These questions measure the effectiveness of the maintenance system and the expertise of the condition monitoring team. If the recommendation was wrong, the follow-up data should expose it. If the recommendation was correct but the work came too late, the organisation failed to respond. If the work order was closed but the machine condition did not improve, the maintenance intervention failed. That is real accountability.
When the team is over-reliant on the CMMS, a work order can be closed while the machine is still defective. The dashboard turns green, but the risk persists. The foreman says the task was not on the system. The planner says no notification was raised. The engineer says the work was not approved. The condition monitoring team says the recommendation was issued. Everyone followed the process, but nobody owned the machine.
Condition-based maintenance requires more than a convenient phrase
‘Condition-based maintenance’ and ‘predictive maintenance’ have become convenient phrases in reports. They sound progressive, but are seldom implemented as an operating model. Condition monitoring is not predictive maintenance when nobody acts on the prediction. An organisation that genuinely wants condition-based maintenance must create capacity for the work it generates. It cannot retain every preventive task, add every new technology and expect the same people to absorb it. Dedicated plant personnel should focus on reliability-centred maintenance work, protected from routine and reactive demands. Somebody must steer that time.
That person may be the reliability engineer or reliability manager. The title is less important than the competence, time and authority attached to the role. The person must have a strong maintenance background, understand condition monitoring and communicate continuously with the condition monitoring team. This is a full-time, highly skilled function. Without authority, the reliability engineer or reliability manager is simply another role trapped inside the same system.
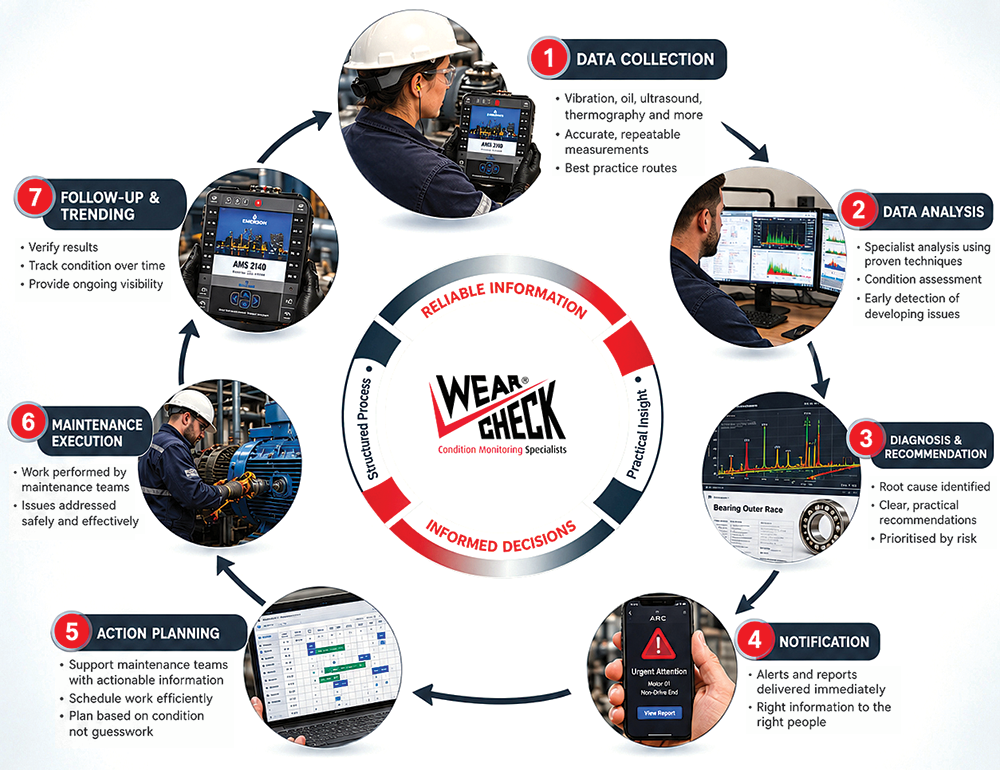
After maintenance, condition monitoring must retest the machine. A closed work order does not prove that the defect was removed. If the condition has not improved, the team must determine why. The real loop is: detect, diagnose, act, retest, confirm.
The system did not fail. The organisation failed when it allowed the system to replace technical judgement, failed to maintain the maintenance strategy and failed to create ownership for the machine. The answer is not a new tool. The schedule must serve the plant. The plant must never be forced to serve the schedule.
| Tel: | +27 31 700 5460 |
| Email: | [email protected] |
| www: | www.wearcheck.co.za |
| Articles: | More information and articles about Wearcheck |






© Technews Publishing (Pty) Ltd | All Rights Reserved
 printer friendly version